
> Biological Data Analysis > Biological Data Visualization > Unleash Interactive Biology: Mastering Data Platforms
Unleash Interactive Biology: Mastering Data Platforms
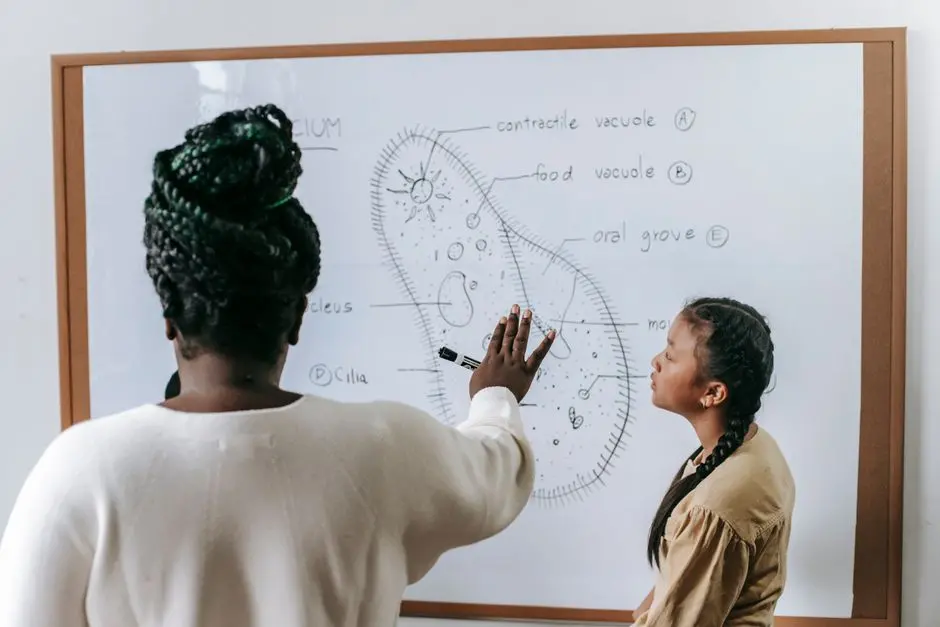
In the relentless pursuit of biological insights, we confront an ever-expanding ocean of data – genomics, proteomics, metabolomics, imaging. Static visualizations, once sufficient, now merely skim the surface. The true power resides in interactivity, enabling us to dissect, filter, and interrogate datasets with unparalleled precision. This article is your tactical brief, a deep dive into the most impactful interactive biological data platforms that redefine our analytical frontiers. We unlock their core functionalities, strategic advantages, and how they empower scientists to transform raw data into actionable knowledge.
Forgeons a future where every biological query is met with dynamic responsiveness. We shall explore how these platforms are not just tools, but extensions of our investigative prowess, allowing us to spot subtle patterns and correlations previously hidden. Understanding and leveraging these platforms is crucial for anyone engaging with biological data, fundamentally enhancing our capacity for adopting effective visual techniques for exploring biological datasets. Prepare to optimize your research workflow, accelerate discovery, and lead the charge in data-driven biological innovation.
The Imperative of Interactivity: Why Static Visuals Fail Us
The volume and complexity of biological data generated today are staggering, far exceeding the capacity of traditional, static visualizations to convey meaningful insights. From high-throughput sequencing to advanced imaging, datasets are often multi-dimensional, hierarchical, and dynamic. Relying solely on static charts and graphs restricts our ability to explore nuances, identify outliers, or drill down into specific data points. This limitation directly impedes discovery, forcing researchers to make assumptions or conduct repetitive analyses across multiple static outputs. The inherent richness of biological data demands a direct, hands-on exploratory interface.
Interactive platforms shatter these limitations by empowering users to manipulate data views in real-time. We can filter, zoom, pan, select, and link disparate data components, revealing hidden patterns and relationships that would be invisible in a fixed image. Consider a genomic dataset: interactively filtering by gene expression levels, tissue type, or disease state allows immediate focus on relevant subsets. This dynamic engagement fosters an intuitive understanding of complex biological systems, accelerating hypothesis generation and validation. Without interactivity, we merely observe data; with it, we actively interrogate and interpret it, transforming observation into discovery.
Key advantages are evident. First, dynamic exploration allows us to iteratively refine our questions, peeling back layers of data as new insights emerge. Second, enhanced contextualization becomes possible by linking different data types or scales within a single interface. Imagine viewing gene expression in the context of protein-protein interaction networks, all within an interactive dashboard. Third, improved data accessibility and collaboration arises as platforms often provide shareable views and collaborative features, breaking down silos. Finally, accelerated insight generation directly results from the rapid feedback loop between user interaction and data visualization. We move from passive consumption to active, strategic data engagement.
Unveiling Genomic and Transcriptomic Landscapes
Genomic and transcriptomic data form the bedrock of modern biology, yet their scale makes them notoriously challenging to interpret without powerful interactive tools. Platforms designed for these 'omics' types allow us to navigate vast stretches of DNA, RNA, and associated metadata with surgical precision. One prime example is the UCSC Genome Browser. It is not merely a viewer; it is an analytical workbench. Users can layer dozens of data tracks—gene annotations, conservation scores, epigenomic marks, variant calls—and interactively zoom from an entire chromosome down to individual base pairs. Its strength lies in its configurability, allowing researchers to customize track visibility and data display to pinpoint specific regions of interest.
Another indispensable platform is Ensembl, which offers a complementary yet equally robust interactive experience. Ensembl provides a comprehensive view of vertebrate genomes, integrating gene predictions, variation data, and regulatory features. Its interactive 'Region in Detail' view allows users to explore specific genomic loci, visualize sequence variation, and even compare syntenic regions across species. The integrated Gene and Transcript views facilitate in-depth analysis of splicing patterns and protein domains, all within a navigable, linked interface. Both platforms are critical for comparative genomics, variant interpretation, and understanding gene structure.
For transcriptomic data, particularly gene expression, platforms like the GTEx Portal (Genotype-Tissue Expression) stand out. The GTEx Portal offers interactive exploration of gene expression across various human tissues. Its interactive tissue distribution plots, gene-gene co-expression modules, and eQTL (expression quantitative trait loci) visualizations allow researchers to quickly ascertain tissue-specific expression patterns or identify genetic variants influencing gene expression. Similarly, the Gene Expression Omnibus (GEO), while primarily a repository, often provides links to interactive visualization tools or allows for direct data download for use in platforms like R/Shiny or Plotly Dash, enabling custom interactive dashboards for specific studies. These platforms empower us to swiftly move from raw sequencing reads to biological insights, driving forward our understanding of gene function and regulation.
Navigating Cellular and Spatial Architectures
Biological research is increasingly focused on the spatial organization of molecules, cells, and tissues. Interactive platforms for imaging and spatial data are revolutionizing how we understand cellular processes and tissue heterogeneity. Tools like ImageJ/Fiji, while open-source and highly extensible, become truly interactive through their powerful plugin ecosystem, enabling real-time manipulation of images, 3D reconstructions, and multi-channel overlays. Users can dynamically adjust thresholds, measure features, and track objects across time series, critical for live-cell imaging or quantitative microscopy. The ability to interactively segment cells and analyze their morphology or protein localization within a spatial context is paramount.
Beyond general image processing, specialized platforms emerge for spatial omics. Technologies like spatial transcriptomics generate data showing gene expression patterns within intact tissue sections. Platforms like the Loupe Browser from 10x Genomics offer unparalleled interactivity for these datasets. Researchers can overlay gene expression maps onto histological images, click on specific tissue regions to see local gene profiles, and explore clustering patterns in a visually intuitive manner. This interactive exploration helps identify spatially distinct cell populations and their associated molecular signatures, which is impossible with dissociated cell analyses.
Furthermore, platforms for single-cell data, such as those built with Seurat (R package) integrated with interactive web applications or Cellxgene (a visualization tool for single-cell data), allow users to explore complex cell populations. We can interactively visualize t-SNE or UMAP plots, select specific cell clusters, and immediately view the differentially expressed genes within those clusters. This dynamic link between embedding space and gene expression data empowers rapid identification of cell types and states. These platforms collectively enable us to not just see, but to understand the intricate architectures governing biological function, from the sub-cellular to the tissue level. We dissect spatial relationships, quantify morphological changes, and uncover the context-dependent roles of genes and proteins.
Advanced Network and Pathway Exploration
Understanding biological systems often means deciphering intricate networks of interactions—protein-protein, gene-regulatory, or metabolic pathways. Interactive platforms are indispensable for visualizing and analyzing these complex graphs. Cytoscape stands as a cornerstone in this domain. It’s a powerful, open-source platform for visualizing molecular interaction networks and integrating them with gene expression profiles and other state data. Users can interactively lay out networks, apply various visual styles based on experimental data, filter nodes and edges, and even perform network analysis algorithms directly within the interface. Its modular plugin architecture extends its capabilities immensely, allowing for specialized analyses like subnetwork identification or enrichment analysis, all within an interactive environment.
For proteomics and protein interaction data, platforms like STRING (Search Tool for the Retrieval of Interacting Genes/Proteins) offer highly interactive network visualizations. STRING aggregates known and predicted protein-protein interactions, displaying them as a network where users can adjust confidence scores, add or remove proteins, and explore functional enrichments. The interactive nature allows us to quickly identify key hub proteins, investigate interaction partners for a protein of interest, and understand the functional context of protein complexes. This direct manipulation significantly streamlines the process of hypothesis generation regarding protein function and disease mechanisms.
Metabolomics, which deals with the small molecule complement of a biological system, also benefits from interactive visualization. Platforms like MetaboLights or specialized tools built on frameworks like Pathway Commons allow for the interactive exploration of metabolic pathways. Users can highlight altered metabolites, trace their flow through a pathway, and identify bottlenecks or perturbed reactions. These interactive pathway diagrams provide a systems-level view of metabolic changes, crucial for understanding disease states, drug effects, or environmental responses. By making these complex networks explorable, we transform static maps into dynamic landscapes of biological activity.
Strategic Implementation and Future Trajectories
Implementing interactive biological data platforms demands strategic foresight. The initial step involves clearly defining your research question and the type of data you aim to visualize. Not all platforms are suitable for all data types or analytical needs. Prioritize platforms with active communities, robust documentation, and continuous development, as biological data science evolves rapidly. Open-source solutions often offer flexibility and cost-effectiveness, while commercial platforms may provide more polished interfaces and dedicated support. A common pitfall is attempting to force-fit data into an unsuitable platform, leading to suboptimal insights or wasted effort. Instead, we must match the tool to the task.
Effective utilization necessitates understanding each platform's unique strengths and limitations. For instance, while a general-purpose tool like R/Shiny or Python/Plotly Dash offers maximal customization for building bespoke interactive dashboards, it requires coding expertise. Pre-built platforms like UCSC Genome Browser or Loupe Browser provide out-of-the-box solutions but might have less flexibility for highly specialized analyses. We must also consider data privacy and security when choosing platforms, especially for sensitive human data. Good practices include regular data backup, version control for analysis workflows, and adherence to FAIR (Findable, Accessible, Interoperable, Reusable) data principles.
The future of interactive biological data platforms is vibrant and convergent. We anticipate deeper integration of Artificial Intelligence (AI) and Machine Learning (ML) for automated pattern detection and predictive modeling within interactive environments. Imagine platforms that not only show you data but also suggest relevant analyses or highlight significant biological features. Furthermore, the rise of cloud-native platforms will enhance accessibility, scalability, and collaborative capabilities, breaking down computational barriers. The focus will shift towards creating more intuitive, user-friendly interfaces that empower biologists with minimal coding experience to conduct complex interactive analyses. The goal remains constant: to transform biological data into definitive, actionable knowledge, driving the next wave of scientific breakthroughs.
Key Takeaways
Interactive Platforms: The New Frontier in Biological Data Analysis
Interactive biological data platforms are indispensable tools for navigating the complexity and scale of modern biological datasets. They empower researchers to move beyond static visualizations, enabling dynamic exploration, real-time filtering, and deeper interrogation of genomic, transcriptomic, spatial, and network data. This interactivity accelerates hypothesis generation, fosters intuitive understanding, and facilitates the discovery of hidden patterns and relationships within vast datasets. We conquer the data deluge by actively engaging with it.
Key Platform Examples and Strategic Deployment
Leading examples include UCSC Genome Browser and Ensembl for genomics, GTEx Portal for transcriptomics, Loupe Browser and ImageJ/Fiji for spatial/imaging data, and Cytoscape/STRING for network analysis. Strategic deployment involves matching the platform to the specific data type and research question, prioritizing tools with active communities and robust documentation, and considering the trade-offs between flexibility (custom code) and ease-of-use (pre-built solutions). Future trends point towards AI integration and cloud-native solutions for enhanced accessibility and collaboration. We optimize our research pipeline for maximum impact.
FAQ
-
How do I choose the right interactive platform for my biological data?
Begin by defining your specific research question, the type and scale of your data (genomic, proteomic, imaging, single-cell), and your technical expertise. Consider platforms specialized for your data type (e.g., UCSC for genomics, Cytoscape for networks). Evaluate factors like community support, documentation, licensing (open-source vs. commercial), and the level of customization required. For unique needs, consider building custom dashboards with R/Shiny or Plotly Dash.
-
What are the common challenges when using interactive biological data platforms?
Challenges often include the steep learning curve for complex interfaces, computational resource demands for large datasets, data integration complexities across different platforms or data types, and ensuring data privacy/security. Data formatting and quality control are also critical; poor data input will yield poor interactive outputs. Persistent data management and version control are essential for reproducibility.
-
Can I integrate data from multiple sources into a single interactive platform?
Yes, many advanced platforms and custom solutions are designed for this. Tools like Cytoscape allow integration of various 'omics data onto network graphs. Platforms built with R/Shiny or Plotly Dash are highly flexible for integrating diverse datasets into a unified interactive dashboard. The key is often in standardizing data formats and identifiers to facilitate seamless integration and meaningful cross-referencing.
-
Are there interactive platforms specifically for educational purposes in biology?
Absolutely. Many public domain platforms like the UCSC Genome Browser and Ensembl are extensively used in education due to their comprehensive nature and user-friendly interfaces for exploring real biological data. Furthermore, initiatives like the Broad Institute's Cancer Cell Line Encyclopedia (CCLE) provide interactive portals to explore cancer genomics data, making complex research accessible for learning and exploration.