
> New Molecule Discovery > Integrated Discovery Workflows > Automate Molecule Discovery: Forge Pathways to Innovation
Automate Molecule Discovery: Forge Pathways to Innovation
The quest for novel molecules, particularly in pharmaceuticals, stands as a crucible of human ingenuity. Yet, traditional discovery pathways often grapple with formidable challenges: glacial timelines, astronomical costs, and the sheer scale of chemical space demanding exploration. These bottlenecks impede our progress, delaying life-saving therapies and stifling scientific breakthroughs. Imagine a paradigm shift, where the very fabric of discovery is interwoven with precision robotics, sophisticated artificial intelligence, and seamless data integration. This is not a futuristic fantasy; it is the immediate, transformative power of automation in molecule discovery.
We embark on an exploration of how automation fundamentally reshapes the landscape of molecular innovation, from initial lead identification to optimized compound validation. We dissect the critical technologies and integrated workflows that drive this revolution, empowering researchers to transcend manual limitations and accelerate the identification of potent, safe, and effective new entities. This article illuminates the path to dramatically shortened discovery cycles, enhanced reproducibility, and unprecedented access to chemical diversity. By embracing these advanced methodologies, we unlock superior hit rates and pioneer more efficient pipelines, pushing the boundaries of what is possible in life sciences. We reveal how embracing these integrated strategies is pivotal for navigating the complexities of
end-to-end processes for discovering novel bioactive molecules, ensuring that every step, from concept to compound, is optimized for speed and success.
The Imperative for Automation: Overcoming Discovery Bottlenecks
The traditional molecule discovery pipeline, a multi-stage marathon from target identification to clinical trials, remains notorious for its inefficiency. We confront an undeniable reality: manual methods are inherently slow, labor-intensive, and prone to variability. Consider the staggering statistics: developing a new drug can take 10-15 years and cost billions of dollars, with failure rates exceeding 90% in clinical phases. A major contributor to this attrition is the inability to thoroughly explore chemical space and accurately predict molecular behavior early in the process. The scale of potential compounds is astronomical—estimated to be >10^60 unique molecules—rendering exhaustive manual screening an impossibility.
This is precisely where automation steps in as a non-negotiable strategic imperative. We must transition from reactive, sequential experimentation to proactive, parallelized workflows. Automation addresses critical pain points:
- Throughput Limitations: Manual screening restricts the number of compounds tested, often missing valuable hits.
- Reproducibility Challenges: Human error, variations in technique, and inconsistent environmental factors compromise data integrity.
- Cost Escalation: Extensive manual labor and specialized reagents drive up research budgets without guaranteed returns.
- Data Volume and Complexity: Modern discovery generates immense datasets, overwhelming manual analysis capabilities.
By integrating robotics, advanced computational tools, and intelligent data systems, we dismantle these barriers. We champion a future where automated platforms execute experiments with unparalleled precision, consistency, and speed, liberating scientists to focus on higher-level problem-solving and innovative hypothesis generation. We are not simply replacing hands with machines; we are fundamentally redefining the operational architecture of molecular discovery, forging a pathway to accelerate breakthrough innovation.
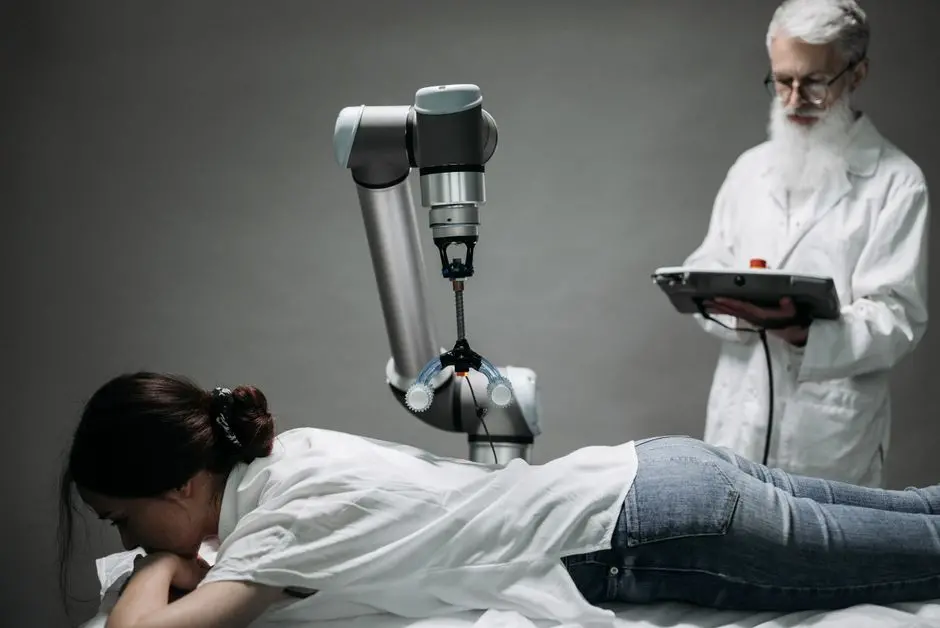
Robotic Platforms and High-Throughput Screening: The Engine Room of Discovery
At the heart of automated molecule discovery lie sophisticated robotic platforms and high-throughput screening (HTS) technologies. These systems constitute the engine room, executing repetitive, complex tasks with unparalleled speed and precision. We deploy liquid handling robots that meticulously transfer minute volumes (nanoliters to microliters) across thousands of assay plates, eliminating human error and drastically increasing experimental throughput. These robotic arms, equipped with multi-channel pipettes and plate stackers, can process hundreds of thousands, even millions, of compounds in a fraction of the time required by manual methods.
Key components of these robotic ecosystems include:
- Automated Liquid Handlers: Precise dispensing, mixing, and serial dilution, critical for dose-response curves and compound plate preparation.
- Plate Readers: Robotic systems integrated with various detection modalities (fluorescence, luminescence, absorbance, time-resolved fluorescence) to rapidly quantify assay results across multi-well plates (96, 384, 1536 wells).
- Automated Cell Culture Systems: Maintaining cell lines and preparing biological assays in a sterile, controlled environment, ensuring consistency.
- High-Content Screening (HCS) Systems: Robotically controlled microscopes coupled with image analysis software, capturing detailed phenotypic data from cells or tissues, moving beyond simple 'hit or miss' to rich biological insights.
- Automated Synthesis Platforms: Robotically controlled reaction setups for parallel synthesis of compound libraries, enabling rapid structure-activity relationship (SAR) exploration.
These platforms collectively transform lead identification from a laborious, low-yield process into a dynamic, data-rich exploration. We maximize the chances of uncovering novel chemical entities by systematically interrogating vast compound libraries against disease targets. The sheer volume of data generated demands robust computational infrastructure, setting the stage for the crucial role of AI and machine learning in processing and interpreting these massive datasets, truly catalyzing the next phase of discovery.
AI and Machine Learning: Navigating Chemical Space and Predicting Outcomes
The true power of automation is unleashed when coupled with artificial intelligence (AI) and machine learning (ML). These computational powerhouses transcend the physical limitations of experimental robotics, enabling us to intelligently navigate the infinite chemical space and predict molecular properties with unprecedented accuracy. We leverage AI/ML algorithms across multiple stages of molecule discovery:
- Virtual Screening and De Novo Design: Instead of physically testing millions of compounds, AI algorithms can computationally screen billions of virtual molecules against a target, predicting binding affinities and selecting the most promising candidates for synthesis. De novo design algorithms generate entirely new molecular structures optimized for specific properties, accelerating the creation of novel chemical scaffolds.
- Predictive Modeling: We train ML models on vast datasets of known compounds to predict critical properties such as ADMET (Absorption, Distribution, Metabolism, Excretion, Toxicity), solubility, and synthetic accessibility. This drastically reduces late-stage attrition by filtering out compounds with undesirable characteristics early in the pipeline.
- Automated Data Analysis and Hypothesis Generation: AI algorithms can rapidly process complex HTS data, identify patterns, classify active compounds, and even propose new hypotheses for experimental validation. This transforms raw data into actionable insights, directing subsequent experimental rounds.
- Reinforcement Learning for Optimization: We implement reinforcement learning to create closed-loop, autonomous discovery systems. An AI agent learns from experimental outcomes, iteratively proposing new compounds or experimental conditions to optimize a desired property (e.g., potency, selectivity), minimizing human intervention.
By integrating AI/ML, we move beyond brute-force experimentation. We instill intelligence into the discovery process, empowering researchers to make data-driven decisions, prioritize optimal candidates, and explore novel chemical entities that would otherwise remain undiscovered. This synergistic approach maximizes resource utilization and drastically improves the success rate in identifying high-quality lead molecules.
Integrated Discovery Workflows: The Synergistic Future
The ultimate frontier in accelerated molecule discovery lies in the seamless integration of all automated components into a coherent, self-optimizing workflow. We move beyond isolated automation islands to architect truly integrated discovery ecosystems where every stage—from design to synthesis, screening, and analysis—communicates and informs the next in real-time. This holistic approach, often termed the 'Design-Make-Test-Analyze' (DMTA) cycle, is powered by advanced informatics and robotics.
Consider an exemplary integrated workflow:
- Design: AI/ML algorithms generate novel molecular structures based on target profiles and predicted ADMET properties.
- Make: Automated synthesis platforms synthesize these proposed compounds with minimal human intervention.
- Test: Robotic HTS/HCS systems screen the synthesized molecules against biological targets, generating high-quality experimental data.
- Analyze: AI algorithms process and interpret the screening data, feeding back insights to refine subsequent design cycles.
This closed-loop system operates with unparalleled efficiency, compressing discovery timelines from months to mere weeks. Data management systems (LIMS - Laboratory Information Management Systems, ELN - Electronic Lab Notebooks) are paramount, ensuring data integrity, traceability, and accessibility across the entire workflow. We champion a modular architecture, allowing for flexible adaptation and integration of new technologies as they emerge. While initial investment and the complexity of integration represent significant hurdles, the long-term benefits are profound: reduced operational costs, vastly improved success rates, and the capacity to tackle previously intractable biological problems. We are forging the future of molecule discovery, where every step is optimized, intelligent, and designed for accelerated innovation.
Key Takeaways
Automation Addresses Core Discovery Bottlenecks
Manual molecule discovery faces critical challenges: slow throughput, high costs, reproducibility issues, and the inability to explore vast chemical spaces. Automation directly tackles these by increasing speed, precision, and consistency across all experimental stages, fundamentally redefining the operational architecture of research.
Robotic Platforms Drive High-Throughput Experimentation
Sophisticated robotics, including automated liquid handlers, plate readers, and automated synthesis platforms, form the engine room of modern discovery. They enable high-throughput screening (HTS) and high-content screening (HCS) of millions of compounds, drastically accelerating lead identification and generating rich biological data with minimal human intervention.
AI/ML Navigates Chemical Space and Predicts Molecular Behavior
Artificial intelligence and machine learning algorithms are crucial for intelligently navigating the vast chemical space. They power virtual screening, de novo molecular design, predictive ADMET modeling, and automated data analysis. This allows for intelligent compound prioritization, early identification of undesirable properties, and data-driven hypothesis generation, moving beyond brute-force experimentation.
Integrated Workflows Create Self-Optimizing Discovery Cycles
The most advanced approach involves integrating all automated components into a seamless Design-Make-Test-Analyze (DMTA) cycle. This closed-loop system, supported by robust data management (LIMS/ELN), ensures continuous feedback and optimization, compressing discovery timelines and maximizing the efficiency of the entire molecular innovation pipeline.
FAQ
-
What is the primary benefit of automation in molecule discovery?
The primary benefit of automation is the dramatic acceleration of discovery timelines, coupled with significant reductions in cost and enhanced reproducibility. By automating repetitive and complex tasks, we boost experimental throughput, minimize human error, and allow scientists to explore vast chemical spaces more efficiently. This leads to faster identification of promising drug candidates, improved success rates, and ultimately, quicker delivery of new therapies to patients.