
> New Molecule Discovery > Combinatorial Chemistry Methods > Forge Precision: Optimizing Combinatorial Library Efficiency for Drug Discovery
Forge Precision: Optimizing Combinatorial Library Efficiency for Drug Discovery
The quest for novel molecules, particularly in drug discovery, remains a formidable challenge, demanding both immense creativity and uncompromising efficiency. Combinatorial chemistry has revolutionized this landscape, enabling the rapid generation of vast molecular repertoires. Yet, the sheer scale of chemical space means that even the largest libraries only scratch the surface, and generating them inefficiently squanders invaluable resources. Optimizing the efficiency of these libraries is not merely an advantage; it is a strategic imperative to accelerate hit identification, lead optimization, and ultimately, therapeutic breakthroughs.
We confront the critical strategies to elevate the productivity of your combinatorial chemistry efforts. From the initial conceptualization of molecular scaffolds to advanced data-driven refinement, we dissect each phase where strategic interventions unlock disproportionate gains. This deep dive empowers you to move beyond mere volume, ensuring every synthesized molecule contributes maximally to your discovery goals. We shall explore how a robust understanding of chemical strategies for generating novel molecular libraries forms the bedrock of an efficient pipeline, transforming your approach to molecular innovation.
Targeted Design: Sculpting Libraries with Precision
We initiate our efficiency conquest at the design phase, recognizing that a library's potential is largely predetermined by its conceptual framework. Random diversity, while sometimes yielding serendipitous discoveries, is inherently inefficient. Instead, we advocate for a rational, targeted design approach. This involves a rigorous assessment of the biological target, if known, and the desired pharmacological properties. We leverage computational tools such as pharmacophore modeling, molecular docking, and QSAR (Quantitative Structure-Activity Relationship) to guide the selection of appropriate scaffolds and building blocks. The goal is to maximize 'druglikeness' and bioavailability parameters early on, thereby filtering out compounds likely to fail in later stages.
A critical strategy is balancing diversity-oriented synthesis (DOS) with target-oriented synthesis (TOS) principles. While DOS expands chemical space, a 'focused diversity' approach – generating diverse compounds around a privileged scaffold or a known active substructure – significantly enhances the probability of finding active compounds. We meticulously select linkers and functional groups that promote favorable ADMET (Absorption, Distribution, Metabolism, Excretion, Toxicity) profiles. Furthermore, incorporating filters based on Lipinski's Rule of Five, Ghose, Veber, or Egan alerts us to potential bioavailability issues before synthesis even commences. This upstream scrutiny is not a luxury; it is a foundational pillar for conserving resources and accelerating downstream success, transforming library generation into a calculated, strategic endeavor.
Synthetic Efficacy: Accelerating Construction, Minimizing Waste
Optimizing synthetic processes stands as a cornerstone for enhancing combinatorial library efficiency. The goal is to construct diverse molecules rapidly, reliably, and with minimal material expenditure. We demand robust, high-yielding reactions that tolerate a broad range of functional groups. Common errors include reliance on unoptimized reaction conditions or using reagents of inconsistent quality, leading to poor conversions, low purity, and ultimately, wasted time and resources. Instead, we champion the adoption of multi-component reactions (MCRs), which assemble three or more reactants in a single step, dramatically increasing molecular complexity and diversity per reaction cycle.
The strategic deployment of automation and flow chemistry techniques elevates synthetic efficacy. Automated platforms execute parallel syntheses with unparalleled precision, reducing human error and accelerating throughput. Flow chemistry, by contrast, offers superior control over reaction parameters (temperature, pressure, mixing), enabling access to otherwise challenging reaction conditions and minimizing byproduct formation. We also prioritize efficient purification strategies, such as solid-supported scavengers or parallel purification techniques, to rapidly isolate target compounds with high purity. Implementing rigorous analytical checkpoints at each synthesis stage – leveraging LC-MS, NMR, and IR – ensures the integrity of intermediates and final products, preempting costly failures. This proactive approach to synthesis ensures that every building block contributes to a viable, high-quality library, rather than to a collection of synthetic artifacts.
High-Throughput Profiling: Unveiling Potency with Speed
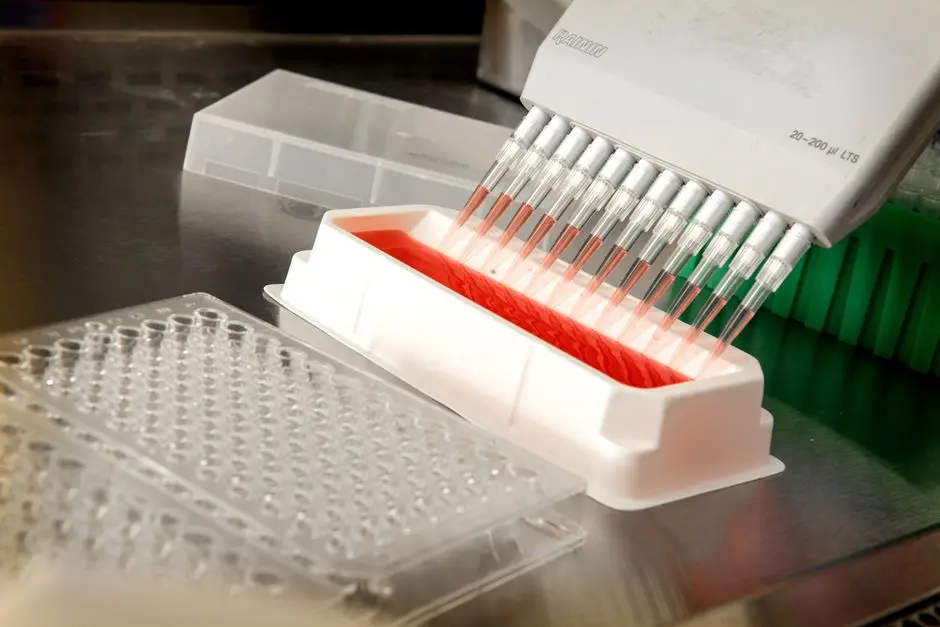
The true value of a combinatorial library manifests during its evaluation phase. Maximizing efficiency here demands a high-throughput, high-fidelity profiling strategy. We must transcend simple screening and embrace intelligent assay design. The transition from biochemical assays to more physiologically relevant cell-based or phenotypic screens, when appropriate, can significantly reduce the attrition rate of compounds later in development. However, these complex assays require meticulous optimization to ensure robustness and reproducibility. A critical consideration is the choice of assay format; miniaturization to 384- or 1536-well plates, coupled with robotics, drastically reduces reagent consumption and increases screening capacity, often allowing millions of compounds to be tested rapidly.
We champion the integration of label-free detection technologies (e.g., surface plasmon resonance, biolayer interferometry) which provide direct binding information, circumventing potential artifacts associated with fluorescent or radiometric labels. Data quality control is paramount: rigorous statistical validation of each assay, including Z-prime factor determination, ensures that hits are not merely noise. Furthermore, implementing multiplexed screening approaches – where multiple endpoints are measured simultaneously – extracts more information from each experiment, maximizing the return on investment for every compound tested. The focus here is not just speed, but also the confidence level in identifying genuine hits, thereby streamlining the validation and lead optimization processes that follow.
Iterative Refinement: Data-Driven Evolution of Molecular Space
The ultimate strategy for sustained efficiency lies in establishing a robust iterative feedback loop. A combinatorial library is not a static entity; it is a dynamic resource that must evolve based on experimental outcomes. We leverage chemoinformatics and advanced data analytics to extract maximum knowledge from every screen. Structure-Activity Relationship (SAR) analysis is not merely a post-screening activity; it must actively inform subsequent library designs. We deploy machine learning (ML) and artificial intelligence (AI) algorithms to identify hidden patterns, build predictive models for activity and ADMET properties, and prioritize future synthesis targets. This transforms the traditional 'design-make-test-analyze' (DMTA) cycle into an accelerated, intelligent spiral of discovery.
Key to this iterative process is the concept of active learning, where the system continuously refines its understanding of chemical space based on new experimental data. We utilize techniques like Bayesian optimization or genetic algorithms to intelligently propose the next set of compounds to synthesize, focusing synthetic efforts on regions of chemical space most likely to yield improved potency or selectivity. This data-driven approach minimizes redundancy, avoids exploring unproductive regions, and systematically converges towards optimal molecular designs. The insights gleaned from both successful hits and inactive compounds are equally valuable, providing crucial boundaries for our exploration. By embracing this continuous learning and refinement, we ensure our combinatorial libraries are not just efficient at their inception, but grow progressively smarter and more targeted with each iteration, driving unparalleled speed in molecule discovery.
Key Takeaways
Strategic Design for Optimal Returns
We prioritize rational, targeted design over random diversity. Leveraging computational tools like pharmacophore modeling and QSAR, we select scaffolds and building blocks that maximize 'druglikeness' and favorable ADMET profiles early on. This upstream scrutiny filters out non-viable compounds, preserving resources for high-potential molecules.
Mastering Synthetic Efficacy
We champion robust, high-yielding synthetic methods, especially multi-component reactions (MCRs), for rapid molecular complexity generation. Automation and flow chemistry enhance throughput and control, minimizing waste. Rigorous analytical validation at each step ensures product integrity, preventing costly downstream failures.
Intelligent High-Throughput Profiling
Our strategy demands high-fidelity assay design, moving towards physiologically relevant cell-based or phenotypic screens. Miniaturization, robotics, and label-free detection technologies boost screening capacity and data quality. Robust statistical validation and multiplexed screening maximize information extraction from every compound.
Iterative, Data-Driven Refinement
We establish a continuous feedback loop using chemoinformatics, AI, and ML. SAR analysis and predictive modeling guide subsequent library designs, focusing synthetic efforts on high-probability regions of chemical space. This active learning approach systematically refines our libraries, accelerating convergence to optimal molecular designs.
FAQ
-
What is the primary goal of improving combinatorial library efficiency?
The primary goal is to accelerate the identification of novel drug candidates and molecular probes while minimizing resource expenditure. By optimizing library design, synthesis, and screening, we aim to increase the hit rate, enhance lead optimization, and bring new therapies to fruition more rapidly and cost-effectively.
-
How do computational methods contribute to library efficiency?
Computational methods are crucial for rational design. They enable us to predict molecular properties (e.g., druglikeness, ADMET), prioritize scaffolds, model interactions with biological targets, and filter out undesirable compounds before synthesis, significantly reducing wasted effort and resources.
-
What are common pitfalls in combinatorial library design that reduce efficiency?
Common pitfalls include designing libraries that are too broad without sufficient focus, neglecting critical physicochemical properties (like solubility or permeability), using unreliable synthetic routes, or failing to validate assay robustness. These issues lead to low hit rates, false positives, and ultimately, a high attrition rate in the discovery pipeline.
-
How does automation enhance combinatorial library synthesis and screening?
Automation significantly boosts efficiency by increasing throughput, reducing human error, and ensuring reproducibility. In synthesis, robots can execute hundreds of reactions in parallel, while in screening, automated liquid handling systems and plate readers enable the rapid evaluation of millions of compounds with consistent precision.