
> Basic Biology Concepts > Introduction to Biological Information Systems > Master Core Biology: Propel Data Science in Biotech
Master Core Biology: Propel Data Science in Biotech
Let's unleash our potential as data scientists in the burgeoning field of biotechnology. The era of massive biological discoveries has transformed laboratories into data goldmines, demanding a new breed of experts capable of turning bytes into clinical and therapeutic insights. This isn't merely about sophisticated algorithms; it's about understanding the inherent language of life itself. Without a grasp of fundamental biological principles, our models risk navigating blind, missing the crucial nuances that distinguish correlation from significant biological causation.
This article builds a robust foundation, indispensable for interpreting, analyzing, and modeling complex biological systems. We will delve into the fundamental mechanisms that govern living organisms, from the molecular to the cellular scale, and how this understanding is the linchpin of all biotech innovation. Prepare to demystify the flow of biological information, from gene to function, to integrate a rigorous physiological perspective into your computational toolkit, and to emerge as a strategic player in the biotech revolution. The success of our data endeavors in this domain hinges directly on our ability to converse with life sciences.
Unlocking the Genomic Code: Foundation for Predictive Models
We are tackling the heart of biological information: the genome. For a data scientist in biotechnology, DNA is not just a sequence of bases; it is the master instruction manual, the score on which all cellular symphonies are played. The Central Dogma of Molecular Biology — DNA > RNA > Protein — is our compass. We understand that proteins are the true workers of cells, carrying out most functions. Any deviation in this flow, whether genetic variations like SNPs (Single Nucleotide Polymorphisms) or indels (insertions-deletions), or complex regulations of gene expression (epigenetics, transcription, translation), has functional repercussions.
Our role is to decipher these variations through sequencing data, gene expression (transcriptomics), or protein profiles (proteomics). We transform this raw data into actionable features for predictive models. For example, understanding how a specific mutation affects protein structure is paramount for drug development. We are aware of the inherent challenges of this data: its massive scale, the inherent noise in biological measurements, and experimental variability. We build robust pipelines to handle these complexities, knowing that the accuracy of our models depends directly on our understanding of the underlying biology.
Cellular Systems: Dynamics, Networks, and Data Integration
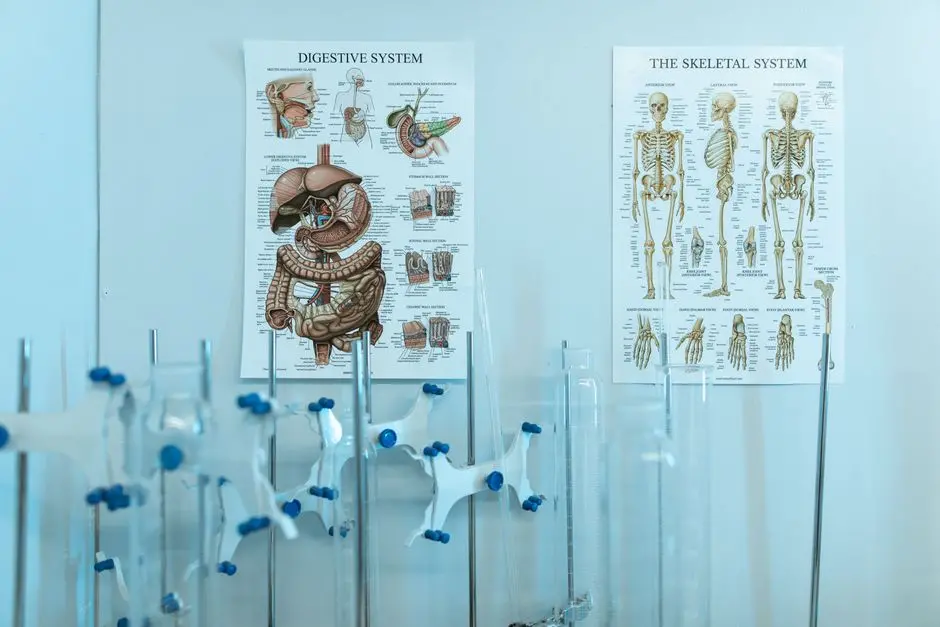
The cell is the fundamental unit of life, our miniature laboratory where thousands of interconnected processes unfold. We do not analyze isolated data points; we examine complex dynamic systems. Each organelle—the nucleus, mitochondria, endoplasmic reticulum—has a specific function, but it is their coordinated interaction that defines the cell's state and fate. Cellular pathways, whether metabolic (energy conversion) or signaling (cellular communication), form intricate networks that our computational tools are perfectly suited to map.
Cell-cell interactions and tissue organization are additional layers of complexity, crucial for understanding diseases like cancer or autoimmune disorders. Advances in multi-omics (integration of genomic, transcriptomic, proteomic, metabolomic data) offer us an unprecedented holistic view. We leverage techniques such as single-cell RNA-seq or spatial transcriptomics to explore cellular heterogeneity and microenvironments. Our expertise lies in integrating these vast datasets to build systems models, identify disease markers, or predict therapeutic responses, adopting a systems biology approach that goes beyond individual genes to embrace network complexity. We transform this complexity into opportunities for deep insights.
Molecular Interactions: From Drug Targets to Therapeutic Design
At the heart of biotechnology lies the manipulation of molecular interactions. For the data scientist, this means understanding how molecules – proteins, peptides, small molecules – assemble and interact. We delve into the principles of ligand-receptor binding, enzyme kinetics, and protein-protein interactions. These mechanisms govern biomolecular function and are prime targets for any therapeutic intervention. The three-dimensional structures of proteins, often obtained through X-ray crystallography or cryo-EM, become critical data points for our rational drug design models. We leverage machine learning to predict binding affinity, mechanism of action, and the potential toxicity of novel chemical entities.
Pharmacogenomics is a powerful application area, where we analyze how an individual's genetic variations influence their response to drugs. Our algorithms can identify biomarkers for targeted therapies or reposition existing drugs for new indications. By harnessing databases of molecular interactions and chemogenomics, we are the architects of the next generation of medicines, guiding discovery through computational approaches. Every molecular interaction is an opportunity for modeling, a potential leverage for human health.
Navigating Biological Complexity: Common Pitfalls and Strategic Approaches
Our journey in biotechnology is not without its challenges. The main pitfall for a data scientist without a strong biological foundation is mistaking intrinsic biological variability (differences between individuals, cells, or time points) for technical noise or experimental artifacts. We must develop a keen sense for biology to distinguish signal from noise. Another classic mistake is equating correlation with causation, a particularly insidious trap in biological systems where multiple factors interact. We always prioritize solid, testable biological hypotheses to guide our analyses.
We are also aware of data biases and the reproducibility crisis in science. To counter these, we adopt best practices: a deep understanding of experimental design, the application of robust statistical methods, and constant, close collaboration with experimental biologists. Their expertise is invaluable for validating our discoveries and refining our models. Our role is not to replace the biologist, but to offer them powerful tools to amplify their research. We forge iterative approaches, where modeling and experimentation mutually enrich each other, driving reliable and impactful discoveries. We integrate critical thinking at every step, ensuring our analyses are not only statistically sound but also biologically relevant.
Key Takeaways
Master the Genomic Blueprint
Comprehend the Central Dogma (DNA > RNA > Protein) as the core information flow. Recognize genetic variations (SNPs, indels) and gene expression regulation as crucial for disease and therapeutic response. Data scientists must interpret omics data (genomics, transcriptomics, proteomics) to build robust predictive models, navigating the inherent scale, noise, and variability of biological information.
Unravel Cellular Systems and Networks
Understand the cell as a dynamic system, where organelles and biochemical pathways form intricate networks. Leverage multi-omics data (e.g., single-cell RNA-seq) to integrate insights across different molecular layers, building a holistic view of cellular states and disease mechanisms. This systems biology perspective is vital for identifying complex interactions and therapeutic targets.
Decipher Molecular Interactions for Drug Design
Grasp the principles of molecular binding (ligand-receptor, enzyme kinetics, protein-protein interactions) as the basis for drug action. Utilize structural biology data and machine learning for rational drug design, virtual screening, and biomarker discovery. Pharmacogenomics, linking genetic variations to drug response, is a key application area for precision medicine.
Navigate Complexity with Critical Biological Insight
Distinguish biological variability from technical noise, and rigorously differentiate correlation from causation. Combat data bias and enhance reproducibility through a deep understanding of experimental design, robust statistical methods, and close collaboration with biologists. Adopt an iterative, hypothesis-driven approach to ensure analyses are both statistically sound and biologically meaningful.
FAQ
-
Why is basic biology crucial for a data scientist in biotech?
Basic biology is paramount because it provides the essential context to interpret complex biological data. Without this foundation, a data scientist risks misinterpreting correlations as causation, designing irrelevant models, or overlooking critical biological nuances. Understanding cellular processes, molecular interactions, and genetic regulation allows us to build biologically informed models, identify meaningful patterns, and contribute to impactful discoveries, moving beyond mere statistical analysis to genuine scientific insight.
-
What are the key biological data types a data scientist encounters?
Data scientists in biotech routinely work with diverse biological data types. These include genomic data (DNA sequences, SNPs, mutations), transcriptomic data (RNA expression levels from RNA-seq), proteomic data (protein identification, quantification, and modifications), metabolomic data (small molecule profiles), and various forms of imaging data (microscopy, medical scans). We also encounter clinical data, phenotypic data, and interaction networks (protein-protein interactions, gene regulatory networks).
-
How do data scientists apply machine learning to biological problems?
We apply machine learning to biological problems in numerous ways. This includes classifying disease states from omics data, predicting drug efficacy and toxicity, identifying novel drug targets, discovering biomarkers, segmenting and analyzing biological images, and modeling complex biological networks. Techniques range from supervised learning (e.g., predicting disease outcome based on genetic markers) to unsupervised learning (e.g., clustering cell types from single-cell RNA-seq data) and deep learning for image or sequence analysis.
-
What are common challenges when integrating biological and computational approaches?
Integrating biological and computational approaches presents several challenges. Data often comes from heterogeneous sources, requiring complex integration strategies. Biological data is inherently noisy, high-dimensional, and prone to batch effects and experimental variability. We must also contend with the 'curse of dimensionality' where the number of features far exceeds the number of samples. Furthermore, ensuring reproducibility, validating computational findings experimentally, and bridging the communication gap between biologists and data scientists are constant hurdles we actively address.