
> Basic Biology Concepts > Introduction to Biological Information Systems > Unlocking Life's Digital Code: Genetic Sequences as Information Systems
Unlocking Life's Digital Code: Genetic Sequences as Information Systems
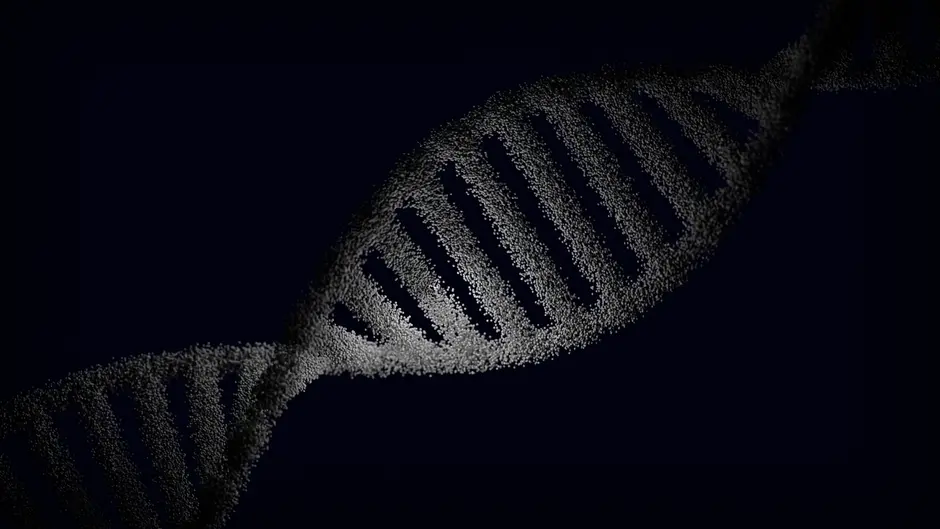
We are forging a revolutionary understanding of biology by exploring a striking and incredibly accurate analogy: our genetic sequences are not mere molecules, but complex embodiments of digital code. Prepare to decipher how DNA strands, with their four nucleotide bases, structure a language of unparalleled sophistication, guiding every aspect of life, from the most basic cell to the most complex organism.
In this article, we initiate a surgical exploration of the principles underpinning this analogy, revealing the power and precision with which nature manages information. We demystify the mechanisms by which this biological "programming" is stored, read, executed, and even "updated" throughout evolution. Understanding that life is encoded as data offers us invaluable insights for medicine, biotechnology, and our fundamental perception of life. Join us on this adventure where bio-optimization meets software engineering to master the flow of biological information, from DNA to function. This is a biological opportunity we are unearthing together, to make futuristic health accurate and exhilarating.
Decoding Life's Core: The Genesis of Biological Information
We must first confront the profound realization that DNA stands as life's ultimate biological hard drive, a molecular repository of information far more complex and efficient than any digital system conceived by humankind. At its core, genetic code operates on a foundational alphabet comprising just four nucleotides: Adenine (A), Thymine (T), Guanine (G), and Cytosine (C). This quartet, seemingly simple, possesses an astonishing combinatorial power. Unlike the binary system of zeros and ones that underpins digital computing, biology employs a quaternary system. Each nucleotide acts as a 'digit,' and their precise sequence dictates everything from cellular structure to organismal behavior.
Consider the analogy: just as a specific arrangement of bits forms a byte, and a sequence of bytes forms a program, the sequential arrangement of these nucleotides forms 'codons' (biological words), which in turn form 'genes' (biological sentences or instructions), and ultimately, an entire 'genome' (the complete operating system of an organism). The crucial point is that this sequence is not random; it carries profound meaning, dictating function with impeccable syntax and grammar. This information density is staggering: the entire human genome, comprising billions of base pairs, fits within the microscopic confines of a cell's nucleus, yet contains instructions for building and maintaining an immensely complex being. Our insider tip here is to grasp that 'information' in biology transcends mere physical structure; it embodies specific instructions, algorithms, and a functional blueprint for life itself. We are not just observing molecules; we are reading an intricate program.
The Central Dogma: A Masterful Information Processing System
The journey from genetic sequence to functional protein is orchestrated by the Central Dogma of molecular biology, a robust and efficient information processing system. This process begins with transcription, where the DNA sequence of a gene is 'read' and copied into an intermediary messenger RNA (mRNA) molecule. We can visualize this as a highly precise data transfer operation, much like loading a specific program module from a hard drive into RAM. The mRNA then travels to the ribosomes, the cellular 'factories' where translation occurs. Here, the mRNA sequence is 'executed' or 'compiled' into a chain of amino acids, which folds into a functional protein. Ribosomes act as highly specialized compilers and interpreters, translating the mRNA's 'bytecode' into the complex, three-dimensional 'executable code' of proteins.
Central to this translation is the genetic code itself – a universal dictionary that maps each three-nucleotide codon in mRNA to a specific amino acid. This code is remarkable for its universality, being nearly identical across all known life forms, a testament to its ancient and foundational role. A key feature of the genetic code is its degeneracy, meaning that multiple codons can specify the same amino acid. This isn't inefficiency; it's a brilliant biological safeguard. It provides a crucial buffer against certain mutations, as a single base change might still result in the correct amino acid, thus preventing detrimental errors. Our good practice in understanding this system is to recognize that the central dogma is not just a theoretical concept, but the active, dynamic process by which genetic information is not merely stored but continually processed, giving rise to all biological functions. We unlock the essence of life's computational power through this understanding.
Orchestrating Function: Regulatory Networks and Genomic Architecture
Beyond the straightforward coding sequences for proteins, the genome is replete with sophisticated regulatory elements – the 'control flow statements' and 'configuration files' that dictate when and where genes are expressed. We delve into promoters, enhancers, and silencers: specific DNA sequences that act as binding sites for an array of regulatory proteins known as transcription factors. These factors function as molecular 'switches' or 'processors,' interpreting signals and deciding whether a gene should be activated or repressed. This intricate network ensures that a liver cell expresses liver-specific genes, and a neuron expresses neuronal genes, despite both containing the identical genomic 'source code.'
Furthermore, we must recognize the critical role of non-coding RNA (ncRNA) molecules. Once dismissed as 'junk,' these RNAs are now understood as powerful regulatory agents, functioning like sophisticated data structures or configuration scripts that fine-tune gene expression, guide chromatin modification, and even regulate translation. This reveals that the genome is not just a linear sequence of instructions, but a dynamic, multi-layered information system. Adding another layer of complexity, chromatin structure and epigenetic modifications (like DNA methylation or histone modifications) act as dynamic 'runtime parameters' or 'access permissions,' altering how accessible genes are to the transcriptional machinery without changing the underlying DNA sequence itself. Our key concept here is that this layered regulation transforms a static, linear sequence into a complex, interactive biological program capable of adapting and responding to internal and external cues. The 'dark matter' of the genome, we discover, is teeming with crucial regulatory information.
Evolution as Software Development: Mutation, Selection, and Innovation
We must conceptualize evolution not merely as a random process, but as an ongoing, iterative 'software development' lifecycle for life's genetic code. Mutations are the 'code changes' – ranging from minor single-base errors, analogous to typos in a program, to large-scale chromosomal rearrangements, akin to refactoring entire modules. These changes introduce variation into the genetic blueprint. Natural selection then acts as the rigorous 'testing and debugging' framework, evaluating these changes in the context of survival and reproduction. Beneficial mutations, which improve an organism's 'performance' in its environment, are propagated and integrated into the 'codebase' of subsequent generations, while detrimental ones are often eliminated. This continuous cycle drives biological optimization.
Consider gene duplication and divergence as a powerful mechanism for 'code reuse' and 'module evolution.' When a gene is duplicated, one copy can maintain its original function while the other is free to accumulate mutations and potentially evolve a novel function, enriching the biological 'software library.' Furthermore, phenomena like horizontal gene transfer, prevalent in bacteria, represent direct 'code sharing' or 'library imports' between unrelated organisms, accelerating adaptive evolution. The emergent properties of biological systems – the stunning complexity and diversity of life – are the result of this iterative, millions-of-years-long 'software development' process. Today, we stand at the frontier of synthetic biology and CRISPR-Cas systems, empowering us to directly manipulate life's 'source code.' We are moving from observing to actively engineering biological functions, opening unprecedented avenues for medicine and biotechnology. The common error is viewing evolution as purely random; it is a sophisticated interplay of random variation and non-random selection.
Key Takeaways
Genetic Sequences as Quaternary Digital Code
DNA utilizes a four-base alphabet (A, T, C, G) to store vast amounts of information in a sequential, highly organized manner, analogous to a quaternary digital system. This precise order dictates all biological functions, forming a complex information system within the cell.
The Central Dogma: A Biological Information Processor
The Central Dogma describes how DNA's information is transcribed into mRNA (a data transfer) and then translated into proteins by ribosomes (execution/compilation). The universal and degenerate genetic code highlights the system's robustness and efficiency in converting genetic instructions into functional molecular machines.
Complex Regulatory Networks for Gene Expression
Beyond coding sequences, regulatory elements (promoters, enhancers), transcription factors, non-coding RNAs, and epigenetic modifications act as sophisticated control structures. They orchestrate gene expression dynamically, determining when and where genes are activated, transforming linear DNA into an interactive biological program.
Evolution: Life's Iterative Software Development
Evolution functions as a continuous 'software development' process where mutations are 'code changes' and natural selection is the 'testing and debugging' mechanism. Processes like gene duplication and horizontal gene transfer further contribute to 'code reuse' and innovation, leading to life's adaptability and complexity. Modern tools like CRISPR represent direct human intervention in this 'source code'.
FAQ
-
Is DNA truly a digital code, or is it merely an analogy?
While it's an analogy, it's remarkably precise and widely accepted in bioinformatics and systems biology. DNA shares key characteristics with digital code: it's discrete (bases are distinct units), sequential (order matters), and informational (it carries instructions for complex processes). It's a quaternary digital system (A, T, C, G) rather than binary (0, 1), but the principles of encoding, storage, and retrieval of information are strikingly similar. This perspective has revolutionized our understanding and manipulation of biological systems.
-
What are the main differences between genetic code and computer code?
While analogous, key differences exist. Genetic code is quaternary, operates in a highly dynamic, self-assembling biological wetware, and its 'execution' (gene expression) is intrinsically linked to its physical structure and environment. Computer code is binary, executed by silicon hardware, and typically operates in a more abstract, isolated environment. Biological code also exhibits immense redundancy and robustness against errors, alongside a capacity for self-repair and evolution, traits often programmed into, but not inherent to, static computer code.
-
How does the "digital" nature of DNA impact biotechnology and medicine?
Recognizing DNA as digital code is foundational to modern biotechnology. It enables us to 'read' (sequence), 'write' (synthesize), and 'edit' (CRISPR) genetic information with unprecedented precision. This perspective drives fields like bioinformatics for analyzing vast genomic datasets, synthetic biology for designing new biological systems, and personalized medicine for tailoring treatments based on an individual's unique genetic 'program.' It transforms biology into an engineering discipline, allowing us to actively design and optimize biological functions.